
Are you using your financial data to its fullest? In today’s fast world, making quick, smart choices is key. Financial companies are now using advanced technologies to stay on top.
Machine learning is changing how we look at and use financial data. With a good machine learning workflow, you can move smoothly through lots of data. This helps you guess market trends more accurately.
This makes your decisions better and increases your profits. As financial markets keep changing, staying ahead means using data to predict what’s next.
Key Takeaways
- Effective use of machine learning can revolutionize financial data analysis.
- Implementing a robust workflow is key for making more money.
- Data-driven predictions can greatly improve your decision-making.
- To stay competitive in finance, you need to use the latest tech.
- Being able to accurately predict market trends can really boost your profits.
The Hidden Cost of Inefficient Machine Learning Processes
Machine learning mistakes can cost a lot of money, as seen in cases like Zillow’s. They lost $500 million trying to predict housing trends. This shows why making machine learning work better is key.
Bad machine learning can waste a lot of resources. It also takes up time and talent that could be used better.
Inefficient workflows can lead to delayed project timelines, missed chances, and less return on investment (ROI) for machine learning projects.

Common Pitfalls That Drain Your Resources
There are a few big mistakes that can hurt your machine learning workflow. These include:
- Inadequate data quality and preprocessing
- Insufficient model selection and hyperparameter tuning
- Lack of continuous monitoring and model updating
As
The key to success in machine learning is not just about having the right data or the most complex models, but also about having an efficient workflow that can turn insights into actions quickly.
This shows the importance of a workflow that can keep up with business needs.
How Streamlined Workflows Translate to Business Value
A good machine learning workflow can really help your business. It makes predictions faster and more accurate.
Streamlined workflows enable organizations to respond more quickly to market changes, grab new chances, and lower the risks of using machine learning.
By making machine learning workflows better, businesses can reach their full potential by leveraging machine learning goals.
This means making each part of the workflow better and making sure the whole workflow for machine learning works well together and meets business goals.
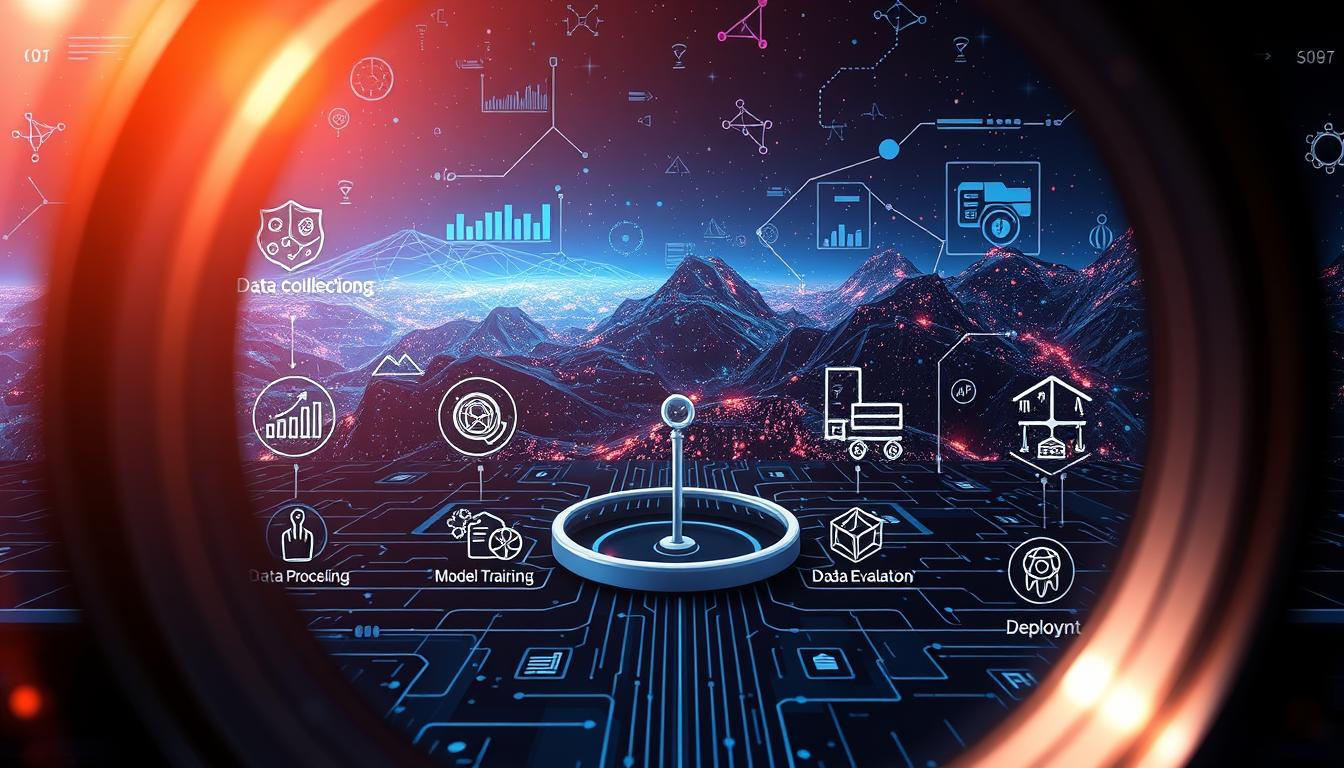
The Complete Machine Learning Workflow Explained
Let’s say you’re part of a cozy pizza shop trying to guess how many Margherita pizzas to make each day.
The machine learning process? It’s like planning your recipe for success—but instead of flour and tomatoes, you’re working with data. Here’s how it unfolds in real life:
Data Gathering: Hunting for Clues
You start by collecting everything that might affect sales: weather reports (rainy days = more orders?), social media buzz, past sales logs, even local events. It’s like asking every customer, “Why did you pick our pizza today?” except you’re gathering numbers instead of stories.
Cleaning & Shaping Data: Sifting the Ingredients
Your spreadsheet looks like a messy kitchen—some entries have typos, others are missing info (“Wait, was that 50 pizzas or 500?!).
You scrub and organize it, just like sifting flour to remove lumps. Suddenly, you notice weekends spike in orders—that’s a pattern worth keeping!
Building the Model: Experimenting with the Recipe
Now, you test different “recipes” to predict tomorrow’s sales. One algorithm says, “Weather matters most!” Another insists, “Nah, it’s all about Instagram likes.” You bake (train) each model on old data, then taste-test (validate) their guesses.
Spoiler: The weather-focused one flops when it’s sunny but your rival pizzeria runs a discount.
Deployment: Serving the Final Dish
Once you’ve got the perfect recipe, you plug it into your daily routine. The model whispers, “Forecast: 85 pizzas tomorrow,” so you prep ingredients, schedule staff, and sleep soundly knowing you won’t drown in leftover dough or disappoint hungry customers.
Why It All Clicks Together
This isn’t just code and charts—it’s solving problems like a detective, chef, and strategist rolled into one.
Whether it’s pizza sales or cancer detection, the magic happens when raw data becomes a tool to make life easier, one slice at a time.
P.S. The best part? When the model messes up (like missing a surprise concert nearby), you tweak it—just like adjusting a recipe until it’s almost as good as Nonna’s sauce. 🍕
Key Components That Drive Successful ML Projects
Machine learning (ML) projects are often hailed as game-changers, but their true potential hinges on meticulous execution.
Behind every successful deployment lies a blend of technical rigor, strategic foresight, and human-centric thinking.
Let’s dissect the four pillars that transform ML initiatives from theoretical exercises into real-world triumphs.
Data: The Bedrock of Intelligence (Quality Over Quantity)
Imagine constructing a skyscraper on shaky ground—no matter how elegant the design, the foundation determines its resilience.
Similarly, ML models thrive on high-fidelity data . This means prioritizing accuracy, relevance, and diversity over sheer volume.
Why It Matters : Biased, incomplete, or noisy datasets lead to flawed predictions. For instance, a healthcare model trained on limited demographics may overlook critical patient variations, risking lives.
Action Steps : Audit data sources rigorously. Validate for representativeness, eliminate redundancies, and address ethical concerns like privacy or bias upfront. Think of data curation as crafting a museum exhibit: every artifact must tell a meaningful, truthful story.
Preprocessing: Unleashing Hidden Signal in the Noise
Raw data is like unrefined ore—it holds value but requires skill to extract. Data preprocessing transforms chaos into clarity by:
Cleaning : Fixing inconsistencies (e.g., misspellings, outliers) and handling missing values (e.g., imputation).
Feature Engineering : Identifying which variables (features) truly influence outcomes. A retail model might prioritize “average purchase frequency” over “time spent browsing” if the latter adds noise.
Normalization : Scaling numerical values to prevent skewed interpretations (e.g., income vs. age).
This stage isn’t just technical—it’s an art. A well-prepared dataset can boost model performance by 20–30%, according to industry benchmarks.
Model Selection: Matchmaking Algorithms to Problems
Choosing the wrong algorithm is like using a hammer to fix a watch. The key is alignment :
What does your problem demand?
Classification Challenges? Try logistic regression for simple binary outcomes or ensemble methods like XGBoost for complex, multi-class scenarios.
Pattern Recognition? Deep learning excels in image or speech tasks (e.g., self-driving cars, voice assistants), but simpler models like SVMs may suffice for structured data.
Interpretability Needs? Industries like finance or healthcare often favor transparent models (e.g., decision trees) over “black-box” neural networks.
Pro Tip: Leverage benchmarking frameworks like AutoML to test multiple models efficiently. Remember, sophistication ≠ superiority—pragmatism wins.
Continuous Evolution: The Lifecycle of ML Systems
A deployed model isn’t a finish line; it’s a starting point. Drift, decay, and obsolescence are silent killers of ML performance. Consider:
Data Drift : A fraud detection model trained pre-pandemic might misspost-pandemic trends.
Concept Drift : Customer preferences shift over time, rendering yesterday’s recommendations irrelevant.
Mitigation Strategies :
- Implement monitoring dashboards to track metrics like accuracy or bias thresholds.
- Schedule retraining pipelines (e.g., monthly updates) with fresh, representative data.
- Embrace MLOps practices for seamless version control and rollback capabilities.
Think of your model as a living entity—nurture it, and it grows stronger; neglect it, and it fades.
Putting It All Together: A Recipe for Impact
Success in ML isn’t a stroke of luck. It’s the result of deliberate choices:
- Invest in data governance to ensure ethical, high-quality inputs.
- Balance technical and domain expertise during preprocessing and feature engineering.
- Adopt a test-and-learn mindset for model selection and iteration.
- Plan for long-term stewardship with automated monitoring and stakeholder collaboration.
Case in point: A global e-commerce giant reduced returns by 18% by refining its data pipeline and retraining models quarterly—a testament to the power of these principles.
Final Thought : Machine learning is as much about people as it is about algorithms. By grounding your projects in these four pillars, you’ll bridge the gap between code and impact, turning abstract models into tools that drive decisions, innovation, and growth. Now go build something that lasts. 🌟
Data Acquisition: Finding the Right Datasets for Profitable Insights
Finding the right data is key to a successful machine learning project. The quality and relevance of your dataset affect your model’s accuracy. We’ll look at how to find and use valuable data.
Identifying Valuable Data Sources
First, you need to find good data sources. Look for datasets that match your problem and have useful information. Internal data sources like customer databases offer insights into your business. External data sources like market trends and social media give a wider view.
When picking data sources, think about quality, relevance, and availability. Also, check for data bias and make sure it represents your problem.
Strategies for Collecting High-Quality Training Data
Getting good training data is essential. Here are ways to do it:
- Data Sampling: Make sure your dataset is a fair sample of what you’re studying.
- Data Labeling: Accurate labels are key for supervised learning. Use active learning to improve labeling.
- Data Augmentation: Use techniques like rotation and scaling to make your dataset more diverse, for images and signals.
These strategies can make your training data better, leading to a more accurate model.
Suggested Reads
9 Python libraries that revolutionize data analytics
24 Uses of python for digital marketing
Leveraging Kaggle and Other Public Datasets
Kaggle is a great place to find and share datasets, including finance and economics ones.
You can use Kaggle datasets to start your projects or add to your own data.
Other public datasets, like UCI Machine Learning Repository or Data.gov, are also useful.
When using public datasets, check their quality and relevance. Also, know about any licensing rules or attribution needs.

By mixing public datasets with your own and using careful data prep, you can build a strong machine learning model. This model will give you valuable insights for profit.
Data Preprocessing: Transforming Raw Data into ML Gold
Effective data preprocessing is key to any successful machine learning (ML) project. It turns raw data into something valuable. Without it, you can’t build a reliable model.
When you explore and clean data, you’re doing more than just removing errors. You’re getting your dataset ready for complex algorithms. These algorithms will make important business decisions for you.
Cleaning and Normalizing Your Data
Data cleaning is more than just removing duplicates or fixing typos. It makes sure your data is consistent and reliable. This includes handling missing values, correcting errors, and normalizing data formats.
Experts say, “Data cleaning is not a one-size-fits-all process; it requires a deep understanding of your data and its limitations.”
“Data cleaning is a critical step in the data science process, and it’s often the most time-consuming part of a project.”
Data Science Handbook
Normalizing your data is also key. It makes sure all features are on the same scale. This prevents any single feature from dominating your model’s predictions. Techniques like Min-Max scaling and Standardization are used for this.
Feature Engineering Techniques That Boost Model Performance
Feature engineering creates new features from your existing data to improve model performance. This can range from simple transformations to complex algorithms. When you prepare data through feature engineering, you’re giving your ML models the tools they need to make more accurate predictions.
- Creating new features based on existing ones
- Using dimensionality reduction techniques like PCA
- Encoding categorical variables effectively
By applying these techniques, you can significantly enhance the performance of your ML models. This turns your data into a true asset for your business.
Handling Missing Values and Outliers
Missing values and outliers can significantly impact your model’s performance. Strategies for handling missing values include imputation techniques, such as mean or median imputation. More complex methods like using ML models to predict missing values are also used.
Outliers need careful consideration. While they can sometimes indicate errors in data collection, they can also represent unusual but valid data points. Techniques like Winsorization or using robust models that are less sensitive to outliers can be effective.
In conclusion, data preprocessing is not just a preliminary step; it’s a foundational element of any successful ML project. By exploring and cleaning your data and applying thoughtful feature engineering, you can prepare data that drives real business value.
Model Selection and Development: Choosing the Right Tools for the Job
The journey from data to profitable predictions starts with picking the right machine learning model and tools. You can choose from simple linear regression to complex neural networks. The right model depends on your problem’s complexity, data quality, and business goals.
Understanding each model’s strengths and weaknesses is key. Linear regression works well for simple, linear problems. But, neural networks handle complex, non-linear issues, needing more data and resources.
From Linear Regression to Neural Networks
The range of machine learning models is wide. Simple models like linear regression are easy to use and understand. But, complex models like deep neural networks can find hidden patterns in data, though they’re harder to train and understand.
When picking a model, weigh simplicity against complexity. Simpler models are easier to understand and less likely to overfit. But, they might not catch all the data patterns that complex models can.
Framework Selection: TensorFlow, PyTorch, and Beyond
After choosing a model, you need to pick a framework to develop and train it. TensorFlow and PyTorch are popular choices. TensorFlow is great for big projects because it supports distributed training. PyTorch is known for being easy to use and flexible, perfect for research and development.
The right framework depends on your needs. Consider the model type, dataset size, and your team’s skills.
Cloud-Based ML Solutions: Google, Microsoft Azure, and AWS
Cloud-based machine learning solutions offer many benefits. They’re scalable, cost-effective, and provide access to pre-built models and frameworks. Google Cloud AI Platform, Microsoft Azure Machine Learning, and AWS SageMaker are top choices.
These platforms make it easier to build, train, and deploy machine learning models. They offer tools for automated machine learning and custom model development, helping you work at scale.
Training and Hyperparameter Tuning: Optimizing for Maximum ROI
Optimizing model training and hyperparameter tuning is key to getting the most out of machine learning. As you explore machine learning, knowing how to do these things well can make a big difference in your project’s success.
Efficient Training Strategies
Using efficient training strategies is vital for top model performance. You can do this by leveraging distributed training. This method lets you spread out your training across many GPUs or machines, making it much faster.
Transfer learning is another smart strategy. It uses pre-trained models as a starting point for your own model. This can greatly reduce training time and boost accuracy, even with small datasets.
- Utilize distributed training to scale your model training.
- Apply transfer learning to leverage pre-trained models.
- Monitor and adjust your training process continuously.
Automated Hyperparameter Optimization
Hyperparameter tuning is a must for better model performance. Automated hyperparameter optimization methods like grid search, random search, and Bayesian optimization can greatly enhance model accuracy. They also cut down on the manual work needed to fine-tune hyperparameters.
- Grid search: Exhaustively searches through a specified grid of hyperparameters.
- Random search: Randomly samples the hyperparameter space.
- Bayesian optimization: Uses probabilistic models to find the optimal hyperparameters.
Balancing Model Complexity and Performance
It’s important to find the right balance between model complexity and performance. Complex models might offer better accuracy but can also lead to overfitting and higher costs. Always regularly validate and evaluate your models on unseen data to make sure they work well and give you the ROI you want.
To strike this balance, consider these strategies:
- Regularization techniques to prevent overfitting.
- Cross-validation to assess model performance on unseen data.
- Simplifying model architecture where possible.
Evaluation Metrics: Measuring What Matters for Business Impact
In the world of machine learning, picking the right metrics is key. It can turn a good model into a profitable one. The secret is to choose metrics that match your business goals.
Beyond Accuracy: Business-Relevant Performance Metrics
Accuracy is important, but it’s not enough. In some cases, a model might just guess the most common answer. Precision, recall, and F1 score give a clearer picture, showing the cost of mistakes.
Andrew Ng, an AI expert, says the right metric depends on your problem. “For example, in medical diagnosis, missing a diagnosis is worse than a false alarm.”
- Precision: The ratio of true positives to the sum of true positives and false positives.
- Recall: The ratio of true positives to the sum of true positives and false negatives.
- F1 Score: The harmonic mean of precision and recall, providing a balanced measure.
Validation Techniques for Real-World Performance
Validation is key to make sure your model works on new data. Cross-validation is a method to check this. It divides data into training and testing parts many times.
Translating Technical Metrics to Financial Outcomes
The main goal of machine learning is to add value to your business. This means turning technical results into money. For example, a model that predicts customer churn can save money by spotting at-risk customers.
To do this, you must understand the cost-benefit analysis of your model. This means looking at the costs of wrong predictions and the benefits of right ones.
By focusing on the right metrics and using good validation, your models can be both effective and profitable.
Deployment Strategies: Taking Your Models to Production
Getting your machine learning models to production is key to their success. It’s about unlocking their power to predict and boost profits. As you move from development to deployment, several important factors come into play.
Scalable Deployment Architectures
A scalable architecture is vital for handling real-world data and user traffic. It must efficiently manage increased loads without losing performance. Cloud-based services like AWS, Google Cloud, and Microsoft Azure provide scalable infrastructure.
Using Docker for containerization and Kubernetes for orchestration boosts scalability. These tools help replicate and manage your application across different environments.
Continuous Integration and Delivery for ML
Continuous Integration (CI) and Continuous Delivery (CD) are key in software development. They are just as important in machine learning. They help you continuously test, validate, and deploy your models.
For ML, CI/CD means automating model testing against new data and deploying updates smoothly. Tools like Jenkins and GitLab CI/CD make this easier.
- Automate testing and validation of ML models
- Streamline the deployment process
- Enhance collaboration between data scientists and DevOps teams
Security and Compliance Considerations
When deploying models, security and compliance are critical. You must protect against attacks and follow data protection laws like GDPR and CCPA.
Strong security measures, like encryption and access controls, are essential. Also, being transparent about model decisions is key for compliance and trust.
Monitoring and Maintenance: Ensuring Long-Term Profitability
To keep your machine learning models profitable, you must monitor and maintain them well. Models work in a changing world. This means their performance and relevance can change over time.
Detecting and Addressing Model Drift
Model drift happens when data changes, making predictions less accurate. Use monitoring techniques like tracking performance and data quality. This helps spot problems early.
Techniques for Drift Detection
- Statistical process control methods to monitor performance metrics
- Data distribution analysis to identify changes in input data
- Concept drift detection algorithms to recognize changes in the underlying data relationships
When you find drift, act fast. You might need to retrain your model or adjust it. An automated retraining pipeline makes this easier, keeping your models current.
Automated Retraining Pipelines
Automated pipelines help you monitor and update models smoothly. They use new data to keep models performing well. A good pipeline includes:
- Data ingestion and preprocessing
- Model retraining and validation
- Deployment of the updated model
Performance Dashboards for Stakeholders
Performance dashboards are key for showing model value. They should be clear and easy to understand. This way, stakeholders know the models are working well.
For better monitoring and maintenance, follow these tips:
- Keep your monitoring tools up to date
- Set up alerts for big changes in performance or data
- Make your retraining pipelines better for new data and changes
Conclusion: Transforming Your Machine Learning Workflow into a Profit Center
You can make your machine learning work profitable by improving your workflow. It’s important to trust your models by keeping detailed records. This includes data prep, model choice, and adjusting parameters.
Scalability and understanding your models are also key. Scalability lets models grow with more data. Interpretability helps you see why models make certain choices. Tools like feature attribution give you a peek into how models work.
Automation is essential for making ML work smoother, cutting down on mistakes, and boosting speed. By automating tasks, you speed up your ML projects and add value to your business. Focusing on these areas can unlock the full power of machine learning, leading to lasting profits.
FAQ
What is a typical machine learning workflow?
A typical machine learning workflow starts with getting data. Then, it involves cleaning and preparing the data. Next, you choose and develop a model, train it, and fine-tune its parameters. After that, you evaluate the model’s performance. Once it’s ready, you deploy it. Lastly, you monitor and maintain it to keep it working well.
Why is data preprocessing so important in machine learning?
Data preprocessing is key because it gets raw data ready for modeling. This includes cleaning, normalizing, and engineering features. It also handles missing values and outliers.
What are some popular frameworks for building machine learning models?
Popular frameworks for building machine learning models include TensorFlow and PyTorch. Cloud-based solutions like Google, Microsoft Azure, and AWS are also widely used.
How do you evaluate the performance of a machine learning model?
Evaluating a model’s performance means using metrics that matter to your business. You also validate its performance in real-world scenarios. Lastly, you translate technical metrics into financial outcomes.
What are some strategies for deploying machine learning models to production?
Deploying models to production involves scalable architectures. You also need continuous integration and delivery for ML. Remember to consider security and compliance.
Why is monitoring and maintenance important for machine learning models?
Monitoring and maintenance are key for long-term profitability. They help detect and address model drift. They also involve automated retraining and performance dashboards for stakeholders.
What is hyperparameter tuning, and why is it necessary?
Hyperparameter tuning optimizes model parameters for maximum ROI. It’s necessary because it balances model complexity and performance.
How can you ensure reproducibility in machine learning workflows?
To ensure reproducibility, document every step and use version control. Implementing automated pipelines also helps.
What is the role of automation in machine learning workflows?
Automation is vital in machine learning workflows. It streamlines processes, reduces errors, and enables scalability.
How can machine learning workflows be transformed into profit centers?
To turn machine learning workflows into profit centers, focus on reproducibility, scalability, and interpretability. Automation is also key. Ensure models are deployed and maintained effectively.